Enes Caglar
Data & AI/ML Engineer.
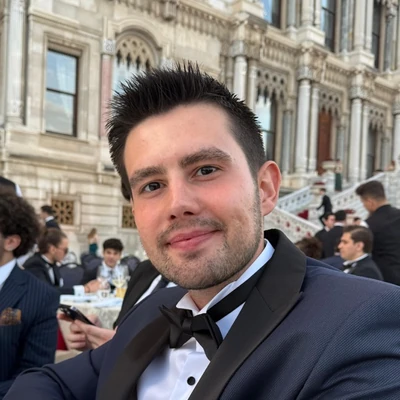
Computer Science & Engineering graduate from Sabancı University. What excites me is following a single piece of raw data all the way through: from messy and unstructured, to clean and usable, to the models and systems the real world runs on.
About Me
Education
B.Sc. in Computer Science & Engineering
Sabancı University
Sep 2021 — Jan 2026
M.Sc. in Information Engineering
Technical University of Munich
Oct 2026 onwards
Hi, I'm Enes! What pulled me into engineering was wanting to understand systems end-to-end, not just use them, from the raw data at one end to the decision or prediction it eventually produces at the other.
That's shaped how I've approached both data engineering and applied ML so far: building Microsoft Fabric pipelines and fraud-detection models at Vispera, running customer segmentation at iLAB, and for my graduation project, going low-level enough to write custom CUDA kernels for real-time inference. Each of these pushed me to look one layer deeper than I probably needed to, which is usually where the more interesting problems turn out to be.
This October, that same curiosity is taking me to the Technical University of Munich for an M.Sc. in Information Engineering, where I'm looking forward to going even further into how these systems are designed end-to-end.
Outside of work, I keep a steady routine: side projects, bodybuilding, playing guitar, and time with the people I care about.
Experience
Professional Experience
Two internships that took me from analytical data work into production data engineering and ML pipelines.
Data & Insights Intern
VisperaJun 2025 — Aug 2025
Istanbul, Turkey
Vispera builds computer-vision and IoT-driven retail shelf analytics. I owned the migration of Power BI reporting projects to Microsoft Fabric — from data architecture to automated quality control.
What I built
- Led the end-to-end migration of Power BI paginated reports to Microsoft Fabric, cutting a scheduled weekly KPI pipeline by ~75% (~45s → ~11s) through column pruning, predicate pushdown and two-week windowing over four joined Delta tables.Migration path: semantic model → .rdl paginated report → SharePoint export → Power Query/Dataflow Gen2 re-ingestion → Fabric Warehouse load.
- Implemented resource-aware incremental refresh in the Fabric pipelines, with dynamic PySpark parameters selected from data volume, job complexity and available compute, and tuned partitioning and parallelism against pre/post runtime checks in the Spark UI.
- Validated the Fabric Warehouse schema and built dimensional data models, including a DAX master date table, to standardize time-based filtering across reports.
- Built a PySpark QC pipeline validating GPS-based audit records against a Haversine-distance check: all 2,208 rows matched the source geodistance within 0.2 m, and 97% within 0.1 m. Pass/fail results post automatically to Microsoft Teams.
- Built a GPS-based auditor fraud-detection pipeline, combining 5 statistical anomaly tests with a DBSCAN clustering comparison, and validated its flags directly against manual reviewer judgments to confirm the method's reliability.
What I found & proposed
- Found ~15% of audit records were being lost to missing GPS coordinates, and proposed recovering the 101 affected records by estimating each store's coordinates from the visit's own start/end positions — projected to cut the loss to ~10%.
Data Science Intern
iLABJan 2024 — Feb 2024
Istanbul, Turkey
iLAB is a group of internet companies that leads digitalization across its verticals through the innovative platforms it builds. Built an unsupervised customer-segmentation pipeline for a large Turkish real-estate classifieds platform, turning 320K+ clickstream sessions into actionable frequency- and value-based user segments.
- Engineered Frequency and Monetary features from 320,148 clickstream sessions across 130,346 unique clients, with category-aware price tiers (rent vs. sale listings scored on separate scales).
- Ran K-Means clustering with elbow-method k-selection (kneed KneeLocator): a 2-feature F/M model at k=7, then an expanded 4-feature model adding scaled click/purchase engagement signals at k=10.
- Visualized high-dimensional cluster separation with t-SNE and profiled each segment by mean frequency, monetary value and engagement behavior.
- Performed exploratory text analysis on listing titles with NLTK tokenization and word clouds.
- Shipped Plotly dashboards profiling listings by category, region, and price.
Projects
Featured Projects
Projects spanning end-to-end data and ML engineering — production pipelines, deployed ML systems, LLM-powered applications, and low-level performance work. Every project here is documented, diagrammed, and runnable in your browser: the demos replay real recorded output, not screenshots.
MobileNet Edge Deployment
Graduation Project — Sabancı University
Profiling and accelerating MobileNetV2 inference — TensorRT FP16 down to 0.30 ms per image at batch 1 on A100, plus prototype FP16 CUDA depthwise/pointwise kernels that beat PyTorch eager by up to 2.1× / 2.6× at the layer level.
Wealth Management Text-to-SQL
LLM + Data Warehouse
Two natural-language-to-SQL approaches over a wealth-management warehouse, measured against each other: retrieval-grounded generation scores 100% execution accuracy vs 88% zero-shot once questions the documentation routes explicitly are excluded.
Glass Box RAG — Customer Support Assistant
Personal Project
A support-drafting RAG pipeline that shows its work: retrieval scores, the exact assembled prompt, and a confidence band that says when the corpus has no answer. Measuring it that way surfaced six real defects — five fixed, one only partially, plus four residual limitations documented.
Inbox Triage
Personal Project
A serverless Gmail triage agent that classifies threads, labels them, drafts replies and writes an executive summary — with a hand-labelled evaluation set that caught a real defect in the classification prompt.
More Projects
A broader sample of data & AI work — full-stack systems, cloud pipelines, LLM agents, and research prototypes.
NBA Data Hub
Full-stack franchise management app with stored-procedure-driven MySQL, a Flask REST API, and a Firebase-backed live support/admin chat.
Flight Ticket Booking Platform
A full-stack booking system with dual-database architecture, server-computed dynamic pricing, and an interactive seat map.
Movie TV Knowledge Graph RAG
A Neo4j knowledge graph of the movie/TV universe, built from Wikipedia with Gemini — plus dedicated Cypher functions for the questions RAG structurally gets wrong.
Multi-Agent Personal Assistant
An AutoGen multi-agent assistant that routes requests across Gmail, Calendar, weather, and web search tools, exposed through a FastAPI service with a self-contained web chat UI.
Resume ↔ Job Description Scorer
A Streamlit app that scores a resume against a job description with Gemini embeddings, then chats through the gaps and generates a full downloadable report with Groq — plus a batch scorer for local datasets.
Document Type Classifier
From a from-scratch CNN to fine-tuned MobileNetV2: a 5-class document classifier (driving license / passport / Turkish ID / social security / other) served behind a Flask web app and REST API.
Turkish Sentiment Architectures — Encoder vs. Decoder vs. Encoder-Decoder
BERTurk, Turkish GPT-2 and mBART-50 fine-tuned head-to-head on Turkish movie reviews — 9 experiments, one clear winner, plus a Streamlit app with a live demo, dataset analysis and the full comparison.
Ethics AI Agent — Gift & Conflict-of-Interest Risk Prioritizer
Reads a free-text ethics declaration and returns category, risk level, the A–H criteria that fired, red flags and a policy-cited justification — a deterministic rule engine, a Gemini-embedding policy knowledge base and an optional LLM layer behind a trilingual Streamlit dashboard.
Machine-Generated Code Detection (SemEval-2026 Task 13)
My ModernBERT-base classifier hit 0.997 validation Macro-F1 — and, like every transformer the team trained, collapsed on the hidden test set, where a TF-IDF + linear SVM (0.459) beat them all. A distribution-shift case study, now with a FastAPI webapp that declares all 11 and serves whichever have weights on disk.
HMM POS Tagger from Scratch
A from-scratch Hidden Markov Model + Viterbi POS tagger for Turkish, improved step by step from 83.7% to 92.8% and shipped as a live in-browser demo.
Real-Time Streaming Data Platform
Planned: an end-to-end streaming pipeline — Kafka ingestion, Spark processing into a medallion-architecture warehouse (bronze/silver/gold), Airflow orchestration, dbt for transformation and data-quality testing, and a live dashboard on top.
Production MLOps Pipeline
Planned: a fraud-detection model taken from training to a monitored production deployment — MLflow for experiment tracking and model registry, a FastAPI serving layer, Evidently for drift detection, and a CI/CD pipeline that triggers automated retraining once drift crosses a threshold.
References
What people I've worked with say
Short excerpts below — full reference letters available on request.
“From the very beginning of his internship, Enes demonstrated exceptional technical ability, problem-solving skills, and a proactive approach to learning. … Beyond his technical competence, Enes is a respectful, reliable, and collaborative individual who easily adapts to team environments. His work ethic and enthusiasm ensured that his internship outcomes exceeded our expectations, and he left a positive impression on everyone he worked with.”
Oğuz Kaan Mavice
Data & Insight Manager
Vispera Information Technologies
“Throughout the course, Enes demonstrated an exceptional ability to integrate computational and biological concepts. He was particularly successful in applying data analysis and algorithmic thinking to biological datasets, which reflects both his technical competence and his capacity to adapt his computer science background to new scientific domains. Enes also stood out for his collaborative spirit. During the course, Enes delivered a well-prepared group presentation on a bioinformatics-related paper, effectively demonstrating his ability to communicate complex ideas with clarity and confidence.”
From a bioinformatics course I took at Sabancı in Spring 2024 — the reference speaks to applying computer science in an unfamiliar scientific domain.
Assoc. Prof. Dr. Saliha Ece Acuner Zorluuysal
Vice President, Department of Bioengineering, Istanbul Medeniyet University
Part-time instructor, BIO310 — Introduction to Bioinformatics, Sabancı University
one last layer — scroll once more
prediction: speed scroller (p=0.78)
efficient. the summary: solid projects above, contact below
All of this runs in your browser. Nothing is tracked or stored.
Let’s talk
Whether it's about the work here, something you're building, or an opportunity you think fits, I'd like to hear from you. I read every message.